Company

BW Toggle LLM Decision Validation

A quantitative experiment on whether an LLM can replace fixed-threshold bad-weather decisions

Period | 2026.03

  • #Python
  • #LLM
  • #Pydantic

Can an LLM make the bad-weather call?

Problem

  • Bad-weather toggles relied on fixed thresholds, and switching to LLM decisions needed evidence
  • Using LLM decisions in operation required checking quality with metrics and mismatch cases

My Role

  • Designed an experiment comparing threshold and LLM decisions on the same data
  • Built an LLM pipeline with Pydantic structured output, batching, retries, checkpoints and token logging
  • Evaluated quality with Accuracy, Precision, Recall, F1 and mismatch analysis

Result

  • Found why hourly aggregation skewed ON decisions to 90.4% and held accuracy near 53%
  • Showed how aggregation unit and input representation affect quality, and set next experiments

Technical Decisions

  • A quantitative comparison before adoption

    To justify replacing fixed thresholds, both methods were run on the same data and scored with Accuracy, Precision, Recall and F1

  • Pydantic structured output

    LLM responses come back in a fixed schema so decisions can be aggregated and compared directly
Running in Production

  • Batching, retries and checkpoints let long experiments resume after failures
  • Token usage logged to track experiment cost
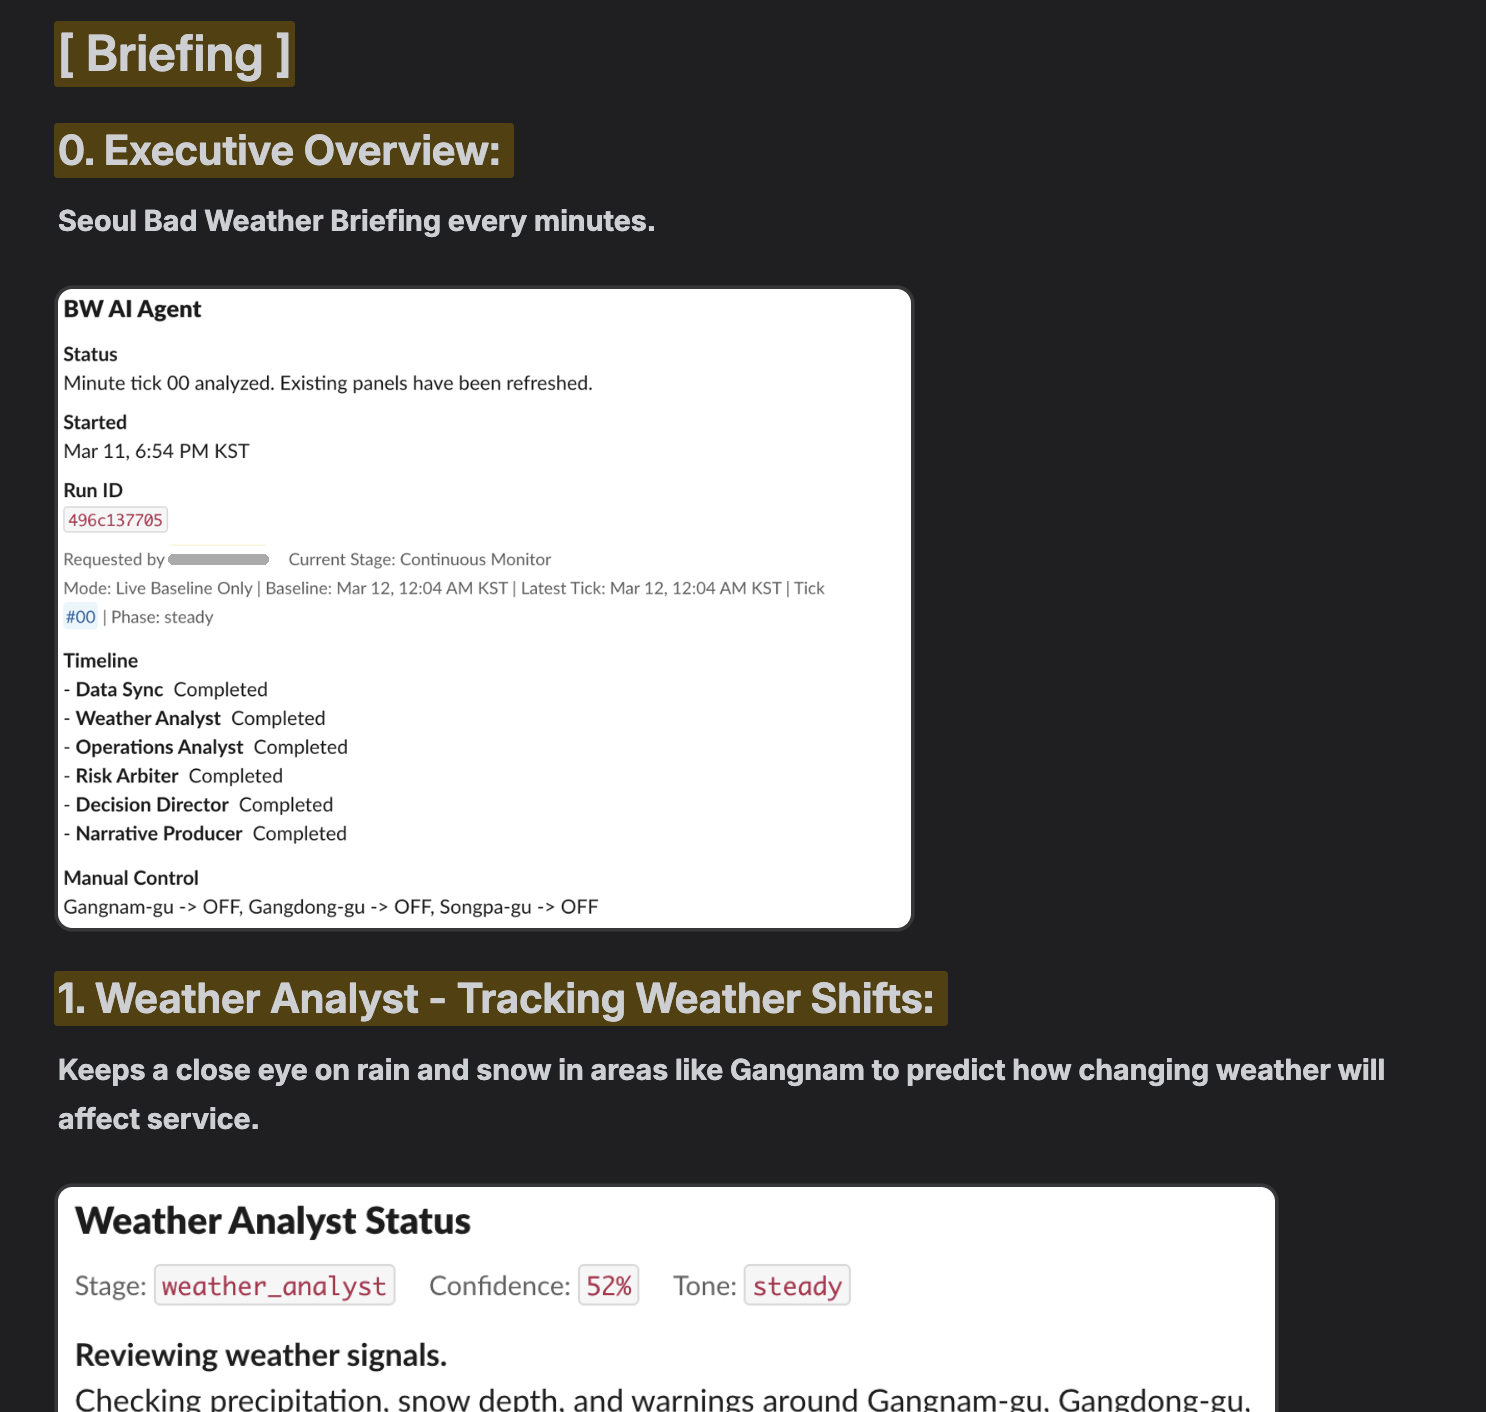
BW AI Agent briefing: stage-by-stage decisions and status (requester masked)